Better databases, better models
Nov 17, 2026
Every now and again, a new type of software workload emerges that is so fundamentally different from what has existed before that it warrants designing a new database around it.
Over the last few years, it has increasingly become apparent that training foundation models is a workload shift of this magnitude. Managing the data to train a large scale language model, video model, or robotics model is for the most part an unsolved problem that looks nothing like the traditional structured data workloads platforms like Snowflake or BigQuery are designed for.
There are a few primary facets by which this takes shape.
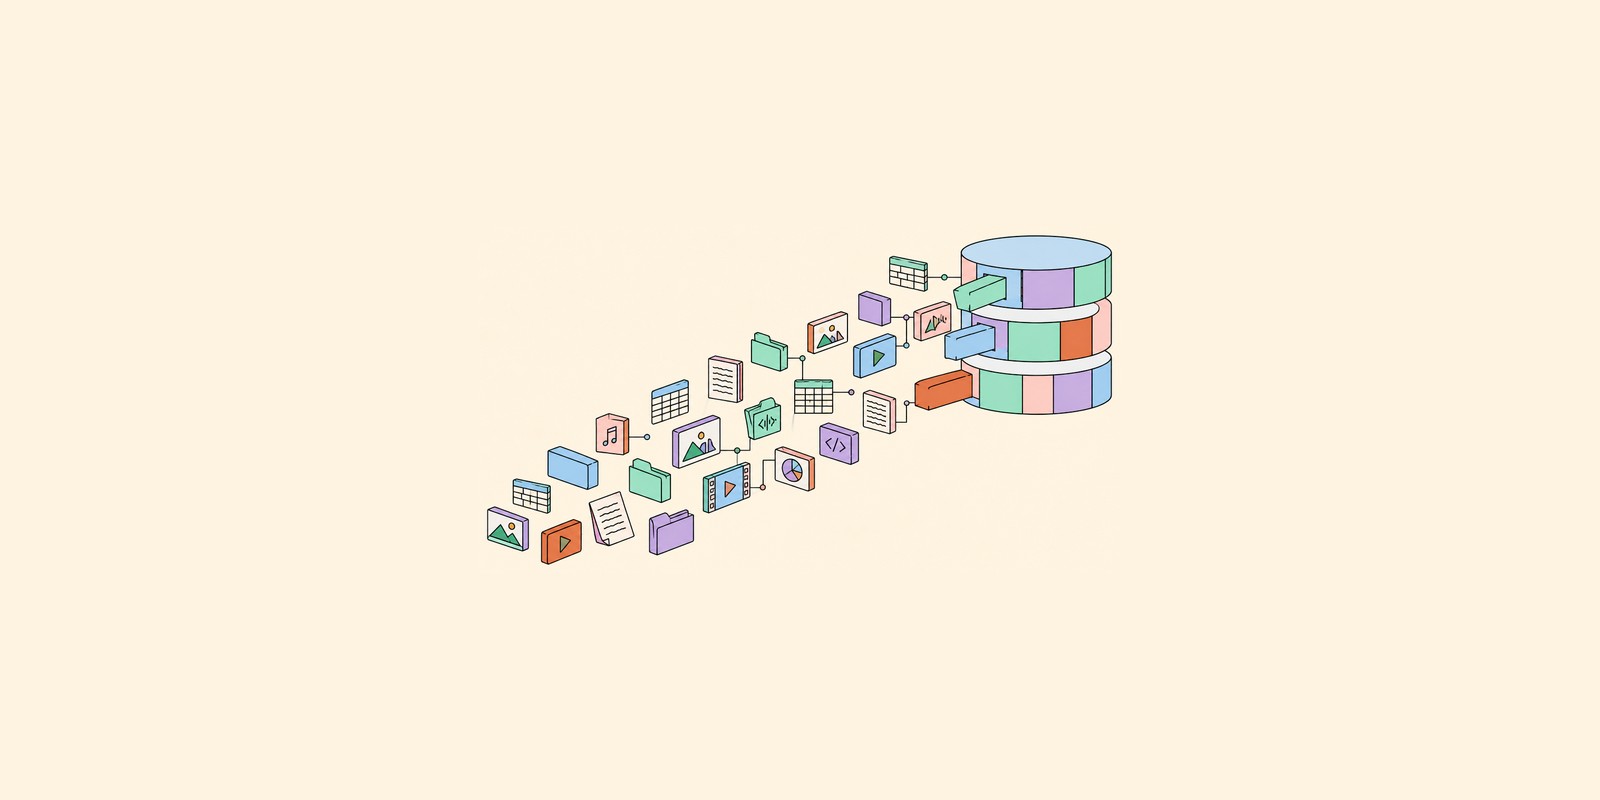
First, the data is unstructured and multimodal. Essentially all modern machine learning models involve large amounts of text, image, audio, and video data - which lack structure, natural schema, and generally don’t fit into the paradigm of traditional data formats. For example, if you are working with video data, how do you store it and search across it? How do you index it? How do you query it? This problem is further exacerbated in more complex model categories like robotics, where you deal with LIDAR data, sensor fusion data, and pose data.
The traditional status quo of storing this type of unstructured data as BLOB objects pointed to from a SQL table simply does not work when such data is your primary data modality.
Second, the query patterns are much more varied and heterogenous. Modern machine learning teams have an interesting blend of random reads (SELECT video_blob WHERE id = 42891332), scans (SELECT AVG(motion_score) FROM clips), aggregate queries (GROUP BY director, year), search queries often via embeddings (table.search("dog barking at mailman")), and then of course training patterns for loading data into memory. This maps to the full ML lifecycle of data curation, data discovery, feature engineering, experimentation, & training. This is vastly different from traditional business intelligence and data warehouse workloads, which is almost entirely scans & aggregates.
Third, there is a much stronger need for high throughput, low cost schema evolution and data experimentation. Machine learning teams run a lot of experiments, which involve testing many permutations of features, derived columns and dataset curations. Traditionally, these sorts of workflows require you to copy your entire table each time. While this is maybe OK if you are working with a one million row table, it starts to fall apart when you are working with a one trillion row table - which is not an uncommon size for a frontier foundation model nowadays.
Unsurprisingly, the first cohort of companies to realize these problems existed (and to start to iterate on solutions to them) was the first set of companies to truly train massive scale AI models - the autonomous vehicle companies. And it was at one of the leading first generation AV companies, Cruise, where Lei stumbled onto the early inklings of what would later become Lance.
Lei is a long-time database systems engineer. He was brought in as tech lead for Cruise’s data processing team to manage all of the data collected by their vehicles and to turn that data into a useful training set for their models. After stumbling through all of the above issues, Lei realized that most existing database technology was not suited for what they needed, and so he started work on an in-house data platform designed to store, process, and manage multimodal AV data at scale.
Coincidentally, at the same time, Lei’s former colleague Chang was also dealing with similar issues running the engineering organization at TubiTV, one of the largest online video streaming platforms. Both were struggling to do data science on top of their massive collection of video data, and were realizing something new needed to be built.
Together, they decided to start LanceDB, a new database company purpose built for solving the problem of at-scale machine learning data management.
They first released Lance as an open source file format designed for multimodal data (you can think of it as an alternative to Parquet - which if you’re not familiar is the most popular data format used by almost all mainstream analytics databases). They then released LanceDB, an open source retrieval library for running search queries on top of the Lance format, which is particularly useful for machine learning teams that need to search over massive multimodal datasets. Since then, they have built out a lot of new features - including a much richer set of platform primitives for running feature engineering, large scale SQL queries and training jobs.
In just a few short years, it is fair to say that the Lance format, and the ecosystem around it, has absolutely flourished. Lance is by far the most commonly used data format for large scale multimodal data, used by essentially every large company you have heard of in AI - ByteDance, NVIDIA, Alibaba, Applied Intuition, Waymo, Netflix, Runway, AMI, Databricks, Luma, the list goes on. It is the fastest growing data and file format of all time. It is now, for example, the default way that Huggingface releases robotics data, and that many data-as-a-service companies deliver data to their clients.
Lance’s broader platform is increasingly being used by many of the largest AI labs in the world. The best models are largely a function of the best data, and curating the best datasets is just as much an infrastructure problem as it is a data science problem. If your best research scientist needs to spend 10 hours to add a new feature to a table, or can’t efficiently cluster their data to identify a better training split, or can’t feed data fast enough to their GPU to max utilization - it is a very bad use of time and money. Yet, this is the status quo of so much of the market.
We believe Lance could be the default database system used by virtually all frontier machine learning labs, and so we couldn’t be more excited to co-lead their Series B with Bessemer. I have known Chang for many years, and have followed Lance’s progress closely. I was initially skeptical of the idea of a data platform oriented towards only AV and robotics companies, but over time I have come to realize that the problems Chang and Lei saw so early on are representative of what every large scale machine learning team in the world are facing.
While Lance has come an incredibly far way in just a few years, in many respects the company is just getting started. Building a database company takes time, and there is so much more that can be done to make model training faster and cheaper. For example, as agents increasingly drive machine learning research, rapid branching and data sandboxes will become far more important, and Lance is actively working on both. Similarly, as reinforcement learning takes up a growing share of model training relative to pre-training, new data infrastructure challenges will emerge in storing and processing large-scale rollouts - and a few teams are already managing theirs on Lance.
Ultimately, while it is difficult to predict exactly how ML models and systems will evolve, what is undeniably clear is that ML systems are ultimately a function of their data, and Lance is increasingly the only player in town designing a database from scratch for the data that will power the ML systems of tomorrow.
The New Implementation Economy
AI is upending the $550B enterprise software implementation industry.
AX is not the new DX, it’s the new UX
Over the past year, Agent Experience (AX) has become one of the most talked-abou...
Plugging in AI, Part 3: “The data center next door will lower your electric bill”
Two years ago, we wrote about the electricity gauntlet – the collision between A...
Meet Soffi: the first truly collaborative workplace for product development
Over the last few years, AI has undeniably transformed the pace of software engi...
Our monthly dispatch for the technically curious